Now in V3.0 — the new industry-leading bar for pre-publication Chinese correction, across text, video subtitles, audio transcription, and image OCR, built for production scale.
Yanlan is a Chinese proofreading system powered by Yanlan-LLM V3.0, a language model trained with a multi-stage RL pipeline, built around the lived constraints of production deployment: false-alarm rates that don't waste editors' time, throughput that handles a daily news pipeline, and a cost profile that runs on a single mid-range GPU. The model handles plain text but also reads video subtitles, audio transcripts, and image OCR — so the corrections happen where the content lives.
Review content in the full workspace
Explore the document layout, subtitle frames, and review suggestions. Yanlan-expand expands individual character differences into phrase-level highlights, keeping each correction in context.
Sample notice for text review
Interactive text review: select an outlined phrase to inspect, accept, or ignore its correction.
Interactive rich-text example: formatting and imagery remain visible. Select a red outline or open Suggestions to review two deliberately introduced sample typos, shown as incorrect → corrected.
Interactive subtitle workspace. Select a timestamp to view its frame, with a red outline around the original error. Inspect, accept, ignore, or reset 9 sample suggestions across 12 subtitle excerpts.
Interactive audio/video example: switch between audio and subtitle findings. Select a subtitle issue to view its still frame and red error outline.
Content review across formats
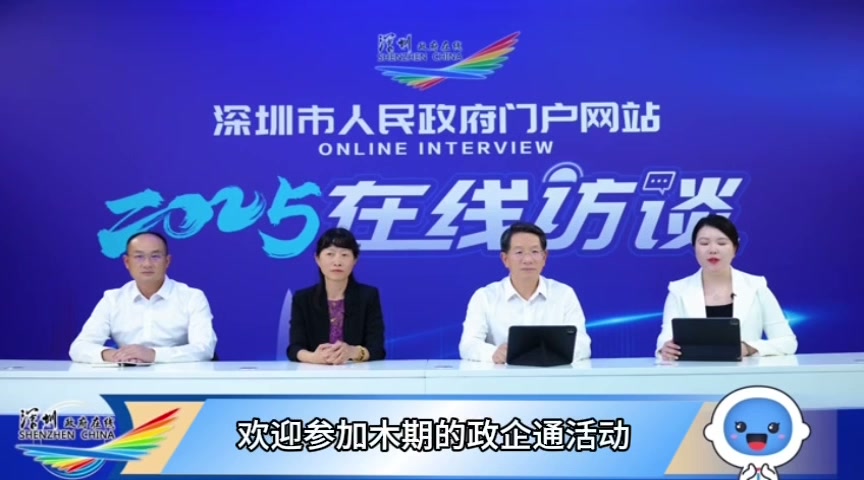
Video subtitle correction
Yanlan connects into the subtitle pipeline and audits every line as it passes — typos, mis-recognised characters, mismatched terms — at 99%+ accuracy and roughly 1–5 seconds per minute of video. Already in use at editorial desks producing multilingual subtitles daily.
Audio transcription correction
ASR transcripts arrive noisy. Yanlan reads them with the audio context in mind, fixes mis-heard homophones, normalises proper nouns, and respects dialectal forms instead of flattening them. 96%+ accuracy across major Mandarin variants.
Identity check on faces
Beyond text: Yanlan includes a face-verification head trained for compliance review on broadcast and streaming content. 98%+ recognition accuracy with a 20–30× speedup over the manual review pipeline.
Regulatory compliance check
Anchored to a corpus of 16,740 Chinese laws and regulations with daily auto-updates, Yanlan flags content that conflicts with current rules — useful for legal review on government, media, and education output.
V3.0 brief
See what changed in Yanlan V3.0.
All eight weighted headline metrics improve over V2.0, with 43 of 47 direct comparisons won. The full release brief separates the evidence, methodology, and deployment implications from the product overview.
Accuracy is only half the requirement. A corrector that is accurate but slow cannot enter production; one that is fast but costly cannot pass a budget review. Yanlan clears both thresholds on a single mid-range GPU, measured against the strongest commercial baselines available.
15×throughput — 30,000 chars/sec
10×lower cost — RTX 4090-class, not H100
0.5%false-alarm rate vs commercial baselines — 10× fewer
99%+video-subtitle correction accuracy
How it works
Yanlan runs as a multimodal perception layer that normalises text, audio, image, and video subtitles into a common token stream, then routes through a classifier that selects between a central dictionary of standard Chinese, a custom dictionary tuned per deployment, and a correction model. A post-processing integration layer merges results before output.
Training is multi-stage RL on top of a Chinese-tuned base: supervised fine-tuning on human-verified corrections, then RL with editorial rewards that explicitly penalise false positives — that last step is what gets the false-alarm rate down to 0.5%.
Yanlan V3.0 is now fully available
Already serving news and publishing organizations, government communications, financial and legal compliance, and broadcast media. Enterprise and government teams: contact us to evaluate Yanlan on your own content.